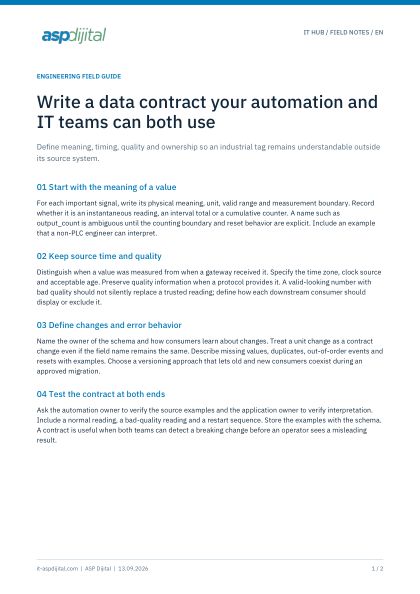
Write a data contract your automation and IT teams can both use
Define meaning, timing, quality and ownership so an industrial tag remains understandable outside its source system.
Analytics is only as good as the signal that reaches it. These guides follow industrial data from the sensor to storage: checking units, timestamps and quality codes, choosing between a historian and a data lake, sizing retention and compression, and cleaning data without removing real events.
A suggested reading order.
Use simple checks for completeness, range, timing and context before trusting a trend or training a model.
Define meaning, timing, quality and ownership so an industrial tag remains understandable outside its source system.
Historians are optimized for fast time-series; data lakes for flexible analytics. The two are complementary - if you design the boundary.
Try what you read.
Inspect CSV data for variation, trends and outliers.
Convert and scale CSV, JSON and Modbus register data.
Estimate data volume from tag count, sampling and retention.
Convert pressure, temperature, flow and other process units in batches.
Generate multi-channel test data with noise, trends and anomalies.
Guides and worksheets to bring to a meeting.
Define meaning, timing, quality and ownership so an industrial tag remains understandable outside its source system.
Use simple checks for completeness, range, timing and context before trusting a trend or training a model.
The analytics model is only as good as the data pipeline that feeds it. The most common data quality failures and how to catch them early.
Define meaning, timing, quality and ownership so an industrial tag remains understandable outside its source system.
A short routine for checking an exported sensor file: timestamps, missing samples, z-scores and outliers, drift and frozen values, and what to do before data reaches a dashboard or a model.
The conversions that cause real mistakes in process data: gauge versus absolute pressure, temperature offsets, volumetric versus mass flow, and normal versus standard cubic meters.
Why timestamps decide whether data can be trusted, where NTP is enough, when PTP is worth the effort, and how to choose a single time source and timestamp convention.
How tag count, sampling interval, payload size, overhead and retention combine into bandwidth and storage numbers, and how deadband and compression change them.
Historians are optimized for fast time-series; data lakes for flexible analytics. The two are complementary - if you design the boundary.
Estimate the data path, separate sampling from storage and validate compression before choosing capacity.
Historians keep very large volumes of samples manageable. Understanding lossless and lossy compression helps you size and tune them.
Every factory needs a historian — but the choice between enterprise platforms, SCADA-native solutions, and open-source time-series databases depends on your scale, budget, and team skills.
Storing and querying industrial time-series data at the edge requires a different mindset than cloud-native architectures. Here is what works in practice.
Raw industrial sensor data is messy. Before any ML model can deliver value, it needs to survive proper preprocessing. Here is the pipeline that actually works in the field.
Principles for modeling industrial data in an Industrial DataOps platform such as HighByte Intelligence Hub: model the plant first, condition data near the source, name consistently and version your models.
Why and how to run compact machine learning models on edge devices with ONNX Runtime: model export, quantization trade-offs, input validation, local buffering and safe model updates.
A historian suits fast time-series queries and operational visibility; a data lake suits long-term analytics across many sources. Many plants use both.
Start by measuring missing data, stale values, clock drift, unit errors and flatline (frozen sensor) behavior.
Describe your machine, data flow or production goal in a few sentences and the ASP Dijital team will reply by email.